Uplink LLC provides a practical framework for dependable uplink connectivity planning, integration, and ongoing operations. This guide explains what “uplink” typically means in telecom contexts, how service provisioning interacts with network design, and which vendor-agnostic requirements matter. Background information covers architecture, compliance considerations, and evaluation criteria used by professionals.
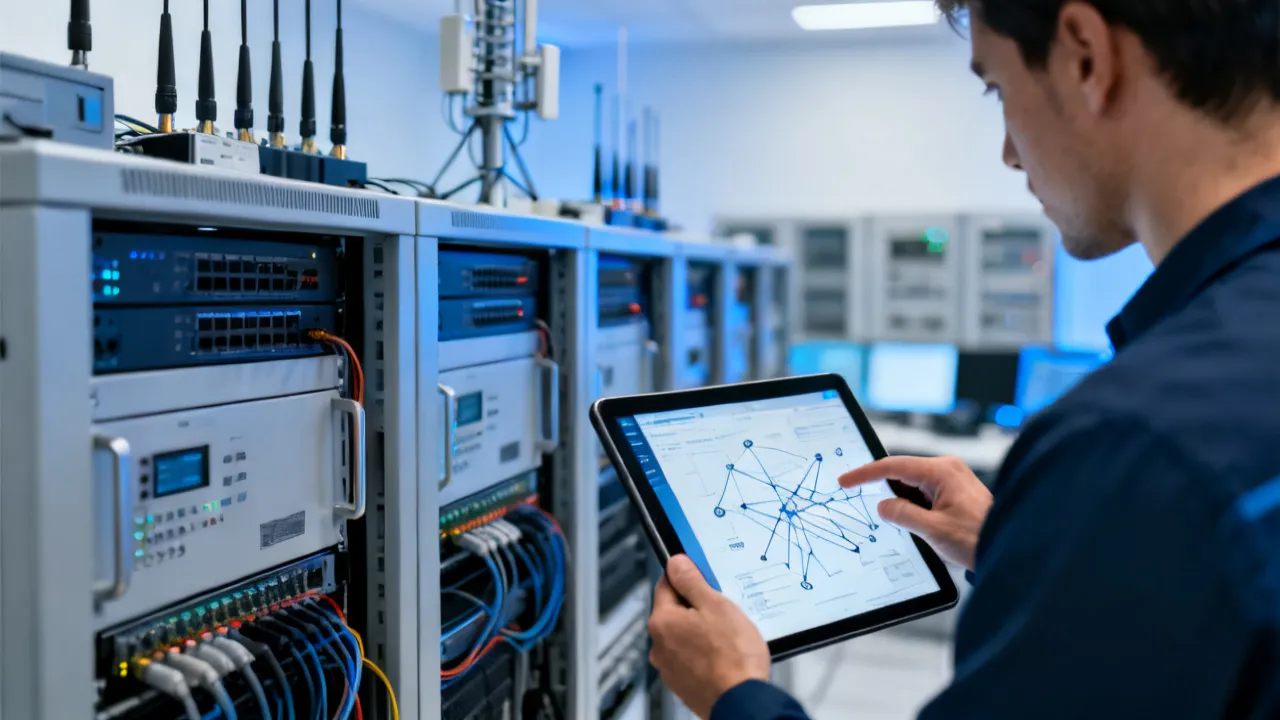
When organizations evaluate Uplink Llc solutions, the core question is rarely just “can we connect?” It’s whether the uplink path is engineered for operational reliability, predictable performance under real workload patterns, and maintainable governance over time. In practice, “uplink” refers to the upstream portion of connectivity—how traffic moves from an organization’s environment toward upstream networks and, where relevant, toward satellite or carrier infrastructure. Choosing an uplink provider (or building an uplink capability) becomes an exercise in aligning network topology, service-level expectations, security posture, and support processes.
For procurement and engineering stakeholders, a reliable uplink is defined by more than raw throughput. It includes latency behavior, resiliency design (e.g., redundancy), clear demarcation between responsibilities, and the ability to monitor, troubleshoot, and scale without guesswork. This guide is written from an industry expert’s perspective to help you evaluate uplink needs systematically—whether you are standardizing connectivity for enterprise locations, improving throughput for field operations, or designing an uplink strategy for critical applications.
Many organizations underestimate how much business value is embedded in the “boring” details: the way routing policies interact with upstream failover, the QoS class mapping across provider boundaries, the reliability of management access channels, and the clarity of incident workflows. Those details influence whether your network behaves like a utility—predictable, observable, and manageable—or like a collection of fragile components that require heroics during outages.
By treating the uplink as a system rather than a pipe, teams reduce operational burden and improve customer experience. The payoff is not only fewer incidents; it’s also faster troubleshooting, lower risk during changes, and a more defensible compliance posture when audits ask how you ensured availability, integrity, and controlled access to communications.
An uplink is the transmission path from a local network or site to an upstream endpoint. Depending on the deployment model, that upstream endpoint could be a carrier aggregation point, an internet exchange, a satellite network gateway, or another managed upstream service. In many modern architectures, uplink performance influences:
From a practical standpoint, if the uplink is poorly planned, every downstream component—firewalls, WAN optimization, cloud connectivity, or application gateways—must compensate. That compensation increases cost, complexity, and the risk of instability. For example, if the uplink introduces variable latency spikes, a WAN optimization layer may interpret them incorrectly, TCP sessions may experience resets, and application-level retries can amplify the problem by generating extra traffic.
Conversely, a well-designed uplink sets the conditions for downstream stability. It provides consistent latency/jitter characteristics, supports the required routing constructs, and offers visibility that allows operators to validate performance and isolate issues quickly. This is especially important for services that traverse multiple overlays (VPNs, SD-WAN tunnels, private cloud circuits, SaaS access proxies) because each layer adds overhead and potentially changes how congestion is perceived.
To make this more concrete, consider the uplink’s role in packet delivery:
Although the exact offerings of Uplink Llc can vary by contract and scope, experienced teams commonly evaluate uplink services and integration options using a consistent set of questions:
Because these evaluations are operational—not marketing-driven—they help teams reduce “surprise failure” risks later in the lifecycle. A common professional pattern is to require proof of behavior in the form of documented metrics, acceptance tests, and a shared runbook. When vendors can’t provide those, teams often assume responsibility for aspects that later become operational burdens.
Another practical evaluation approach is to treat uplink selection as part of a broader control plane and data plane design exercise. That means confirming not only how user traffic flows, but also how the service’s management plane is reached (e.g., SNMP/telemetry endpoints, remote management access channels, authentication methods, and access restrictions). Many outages start as management-plane issues: an operator cannot reach the device or service to gather evidence or apply remediation quickly.
Reliable uplink connectivity is a central element of modern WAN and edge architectures. Industry top practices emphasize observability, controlled changes, and resilience. Organizations often adopt model-driven operations where configuration changes are logged, validated, and rolled out safely. These practices align with widely discussed operational frameworks in networking and IT service management.
For background, standards and guidance typically stress:
While vendors may market outcomes, objective decision-making requires traceable measures. Credible sources for telecom reliability and service management principles include documents published by international bodies such as the ETSI (European Telecommunications Standards Institute) and service management frameworks referenced by ITIL (AXELOS). These sources inform how organizations think about reliability, incident management, and service governance.
In practice, governance is where many organizations gain or lose long-term value. Uplink projects frequently run into issues not because the technology fails, but because change windows are poorly coordinated, documentation is incomplete, or ownership boundaries are unclear. Governance disciplines help ensure that when something goes wrong, teams know what to do next—without improvising under pressure.
To align uplink design with governance, teams typically define:
In real projects, the very successful uplink deployments share a common pattern: requirements are translated into technical specifications, specifications are validated via testing, and integration is governed by documented ownership. Below is an approach that teams can adapt regardless of vendor.
Before any contract details matter, the organization must translate business priorities into network requirements. Business priorities often come in the form of uptime targets, application performance expectations, regulatory commitments, and operational capacity constraints (e.g., “we can’t have support engineers on-call 24/7 for every site”). Those priorities translate into measurable network behaviors and operational practices.
In other words, uplink planning is a two-track effort:
The organizations that succeed tend to run both tracks in parallel. If engineering design is strong but operations are weak, troubleshooting still stalls. If operations are mature but engineering requirements are vague, incidents and degradations still occur—just with faster detection and recovery.
Use this structured approach when assessing Uplink Llc or any uplink supplier. The goal is to prevent “design-by-assumption” and to make performance and ownership measurable from day one.
Even a strong vendor relationship can fail if foundational requirements are unclear. Professionals typically insist on the following conditions before signing off on an uplink design or service transition:
Additionally, teams should verify procurement-level constraints that often cause hidden delays:
The table below is intended to help you compare decision factors—not to replace vendor-specific documentation. Since you may be evaluating Uplink Llc as part of a broader connectivity program, use these criteria to structure discussions with suppliers and internal stakeholders.
| Evaluation Area | What to Verify | Why It Matters |
|---|---|---|
| Service Scope | Installation, provisioning, monitoring, and incident support boundaries | Prevents delays during troubleshooting and avoids ownership disputes |
| Performance Metrics | Latency/jitter/packet loss expectations and throughput measurement approach | Ensures application experience aligns with business needs |
| Resiliency | Redundancy model and failover behavior, including testing cadence | Improves recovery time objectives during upstream disruptions |
| Security Posture | Encryption expectations, management-plane access controls, segmentation support | Reduces attack surface and supports compliance requirements |
| Operational Visibility | Telemetry access, reporting frequency, and alerting logic | Enables proactive monitoring and faster root-cause analysis |
| Change Management | Planned maintenance process, rollback plan, and notification workflow | Minimizes risk from configuration changes |
| Commercial Clarity | Contract terms, operational commitments, and escalation procedures | Aligns expectations on timelines, service continuity, and support behavior |
You asked to incorporate price information and supplier details where available. In this prompt, no specific pricing figures, rate cards, or supplier identity details (beyond the term Uplink Llc) were provided. In professional procurement, that absence matters: pricing for uplink services is usually shaped by bandwidth commitments, installation complexity, geographic factors, redundancy requirements, and service-level terms.
Accordingly, the top practice is to evaluate commercial proposals using structured comparability:
To avoid “lowest price wins” outcomes that create long-term operational costs, procurement teams can also evaluate commercials using a few additional dimensions:
In many uplink environments, it’s not the recurring bandwidth fee that surprises teams—it’s the cost of operational readiness: professional services, on-site labor for testing, equipment replacement, and additional support subscriptions needed to achieve acceptance criteria. Commercial evaluation should therefore include operational readiness costs, not only network service rates.
If you can share the relevant pricing and supplier scope text you want used, the article can be updated to reflect those specifics accurately.
You specified a rule about replacing any city/country placeholders with “nearby”. No explicit city or country tokens were included in the keywords provided, but the guidance still matters for planning. In practice, teams often describe rollout scope in terms of “nearby” coverage—meaning installations and upstream connectivity availability that fits within operational travel, service windows, and support coverage realities. This localized framing is common in project planning discussions because physical logistics and on-site testing requirements are influenced by geography.
When stakeholders say they need coverage “nearby,” they’re often signaling constraints like:
Even if the uplink is primarily a network service, the operational reality still includes installation coordination, cross-team scheduling, and testing logistics. For example, if acceptance testing requires site commissioning and provider technicians must be present, then “nearby” coverage affects not only technical feasibility but also the project’s timeline and risk profile.
Localization also affects performance baselines. The upstream path characteristics can vary by region due to peering patterns, congestion levels, and infrastructure maturity. Teams that ignore this variation can end up with “average” expectations that do not match what sites experience in practice.
Seasoned engineers and program managers usually see the same failure modes. Avoiding them early reduces both downtime risk and project friction:
Beyond these, there are additional pitfalls that frequently appear in more complex environments:
Many uplink evaluations stop at generic “uptime” and “bandwidth.” In professional practice, teams define reliability in measurable terms tied to user experience. That includes metrics for availability, performance degradation, and time-based behaviors during change and failure.
While the specific metrics depend on the organization’s needs, a strong evaluation commonly includes:
When Uplink Llc is being evaluated, requesting evidence for these metrics—ideally in the form of acceptance tests, measurement reports, or historical performance data—is often the difference between confidence and uncertainty.
Security is frequently discussed as if it only exists in firewalls and endpoint configurations. In reality, uplink routing and service design can strongly influence your security posture. Professionals therefore treat security integration as a cross-layer topic.
Key security considerations include:
Additionally, teams should confirm how logs are handled. Security teams often require the ability to correlate network changes with security events. If logs and telemetry are not available or are delayed, incident response suffers. Therefore, contract scope should include log access expectations and time synchronization requirements for meaningful correlation.
Operational teams often struggle when customer-side logs and provider-side indicators disagree. For that reason, professionals aim for a “shared truth” model: both parties should rely on the same definitions and timestamps so that symptoms map to underlying causes.
Practical observability practices include:
When observability is well-managed, teams reduce time spent guessing. When observability is weak, even a minor incident can expand into prolonged downtime due to uncertainty. This is where uplink planning and operational governance converge—telemetry is both a technical and procedural requirement.
Failover testing is essential, but it can also create risks if done carelessly. Professionals balance verification with safety by applying test design principles similar to change management.
Effective failover testing typically includes:
When Uplink Llc or any provider is involved, failover testing should be coordinated so that both customer and provider understand what constitutes a successful test. Otherwise, you may complete a test that is technically “successful” from a provider perspective but fails to meet your application-level expectations.
Capacity planning for uplinks is often misunderstood because organizations think bandwidth is static and consistent. In reality, traffic is bursty, application patterns change, and overhead from encryption/tunneling evolves with configuration and scaling.
Professional capacity planning incorporates:
Then connect those plans to uplink service terms. If the uplink provider oversubscribes beyond certain thresholds without clear behavior definitions, your operational risk increases. Acceptance criteria and contract definitions should therefore explicitly address how performance behaves under realistic load.
“Uplink Llc” is used here as a reference to an uplink-related provider or entity. In general, uplink services involve upstream connectivity design, integration, provisioning, and ongoing operational support. The exact scope depends on the contract and technical engagement model.
Use comparable acceptance criteria and scope definitions: performance metrics (latency/jitter/packet loss), resiliency/failover design, monitoring visibility, security responsibilities, support escalation workflow, and change management terms. Also compare the operational maturity reflected in runbooks, reporting cadence, and joint incident processes—not only the advertised bandwidth.
No. For many applications, latency and jitter matter as much as throughput. A well-architected uplink also ensures predictable behavior during congestion and during partial degradations. Teams should validate performance under load and confirm QoS handling for real-time or mission-critical traffic classes.
Common approaches include diverse upstream paths and automated failover mechanisms. The key is to verify how failover is triggered, how quickly services recover, and how failover behavior is validated during tests. Also confirm how failback works, and whether reconvergence creates stability issues or repeated session interruptions.
Request technical scope documentation, responsibility matrices (customer vs. provider), acceptance testing methodology, monitoring/reporting descriptions, escalation procedures, and change management expectations. Also ask for interface specifications, MTU/QoS mapping documentation, and measurement definitions (where latency/jitter/packet loss are measured and how often).
Yes, many teams phase deployments: start with a pilot site, complete integration testing, then roll out additional locations or redundancy upgrades after lessons learned are applied. A phased plan still requires measurable acceptance criteria. If you phase, define a consistent baseline so performance at later sites remains comparable to the pilot results.
Look to internationally recognized standards and frameworks such as ETSI for telecom-related standards and AXELOS ITIL guidance for service management concepts. For reliability-focused engineering practices, ensure sources are reputable and align with your regulatory and operational context. Additionally, consider internal standards that reflect your organization’s security, change governance, and incident response maturity.
Choosing or working with Uplink Llc should be approached as an end-to-end engineering decision: define measurable requirements, confirm integration compatibility, insist on resiliency behaviors that are tested, and establish operational governance so issues can be detected and resolved quickly. When procurement and engineering align around objectives—rather than assumptions—uplink connectivity becomes a stable foundation for applications, security controls, and good scalability.
A final practical takeaway is to institutionalize learning. After each site rollout, each failover test, and each incident, update acceptance criteria, monitoring thresholds, and runbooks. That converts one-time projects into an evolving capability. Over time, this reduces operational friction and makes future procurement cycles faster, because you already know which uplink behaviors matter most for your specific application mix.
If you provide any specific pricing terms, supplier scope, or contractual constraints you want reflected, I can revise this article to incorporate those exact details while keeping the content objective and SEO-aligned.
Striking the Perfect Balance: Navigating Premiums and Out-of-Pocket Expenses in Senior Insurance Plans
Explore the Tranquil Bliss of Idyllic Rural Retreats
How to Make Lasting Memories at Disneyland Attractions
Affordable Phones and Plans for Seniors
Affordable Full Mouth Dental Implants Near You
Unlock the Top Kept Secrets to Finding Your Ideal Dentist for Flawless Dental Implant Results!
Discovering Springdale Estates
Unveiling RS Sul Telecom Services
The Guide to Car Trading
Unveiling RS Sul Telecom Services
RS Sul Telecom emerges as a prominent entity in the telecommunications industry, providing reliable services across various regions. This article delves into the offerings of RS Sul Telecom, the benefits it presents to both individual and business clients, and its impact on the modern telecom landscape.
Understanding Rlock Advpl in Business
Rlock Advpl represents a pivotal advancement in business software solutions, offering enhanced security and efficiency for enterprise resource planning systems. This article delves into the intricacies of Rlock Advpl, its application in modern businesses, and the benefits it offers in streamlining operations and safeguarding data. As an expert tool, Rlock Advpl is essential for businesses looking to optimize their IT infrastructure.
Unveiling Atranet Innovation
Atranet represents a cutting-edge concept in networking technology. Harnessing its capabilities can transform digital communication by providing seamless connectivity. Designed to optimize data transfer, security, and efficiency, Atranet is shaping the future of how we connect and share information. This article delves into its structure, applications, and potential impacts on industry practices and consumer experiences.
Understanding Polysulfide Adhesive Applications
This comprehensive guide explores the applications and benefits of polysulfide adhesive, highlighting its unique properties and widespread use in construction, aerospace, and automotive industries. Known for its flexibility and resistance to various environmental factors, polysulfide adhesive is a key component in sealing and bonding applications, providing durability and reliability in demanding conditions.
Comparing Vtex with Salesforce Commerce
This article provides an in-depth comparison between Vtex and Salesforce Commerce, two leading digital commerce platforms. Each offers unique features suited to different business needs. Vtex is renowned for its collaborative commerce approach, while Salesforce Commerce shines with its comprehensive customer relationship management capabilities. Explore their differences, strengths, and insights from industry experts.
Understanding the Latest Chrome Version
This article delves into the intricacies and features of the latest Chrome version. Chrome, developed by Google, is one of the very popular web browsers globally, known for its speed, simplicity, and security features. Each update aims to enhance user experience through improved functionality and performance. Understanding these updates is crucial for both everyday users and developers.